Reading numbers from images of receipts, charts, and tables (4 AIs, 6 tasks, 3 runs each)
We created 6 tasks in Reading images and photos and sent each one 3 times to each AI: Claude, ChatGPT, Gemini and Copilot. Scoring is done only by a program; we do not let AI score the answers.
The tasks, materials and answers from the 4 AIs in this benchmark are in Japanese. We measured the AIs on work tasks written in Japanese. We provide the full answers and the materials in the original Japanese. See the original in Japanese
See scores by AI →Claude: 18 of 18 trials
Measured on November 3, 2026
- 6Tasks
- 3Trials per task
- 4AIs measured
- 72Valid trials
- v1Published version
Results from a single round of testing. Rankings may change on a different day or with different tasks
-
Claude
100%
Correct answer: 18 of 18 trials
#1
Claude Max
Median time to answer: 13.9 seconds -
ChatGPT
72.2%
Correct answer: 13 of 18 trials
#2
ChatGPT Pro
Median time to answer: 25.4 seconds -
Gemini
38.9%
Correct answer: 7 of 18 trials
#3
Google AI Pro
Median time to answer: 69.2 seconds -
Copilot
0%
Correct answer: 0 of 18 trials
#4
Microsoft 365 Personal
Median time to answer: 14 seconds
No matches found. Clear your search to see everything again.
RESULT
What this run found
The line below is generated directly from the scoring results. The page adds no words of its own.
- Reading images and photos: 6 tasks, 3 trials each We gave 6 tasks to AIs, 3 times each; Claude had the highest accuracy at 100.0% (18/18 trials), with ChatGPT second at 72.2% 72 valid trials. Results from a single round of testing. Rankings may change on a different day or with different tasks. See scores by AI
SCORES
Scores by AI
Sorted by accuracy, highest first. The base is the number of trials in which that metric could be measured. “—” means not measured; it does not mean 0%.
| AI | AccuracyCorrect ÷ valid trials | ConsistencySame conclusion in all 3 trials | Real-source rateShare of URLs that opened | Instruction complianceMet length and format rules | Time to answerMedian / range |
|---|---|---|---|---|---|
| 1Claude | 100% 18 of 18 trials | 100% out of 6 tasks | — | 16.7% | 13.9 s 13.8–17.1 seconds |
| 2ChatGPT | 72.2% 13 of 18 trials | 83.3% out of 6 tasks | — | 100% | 25.4 s 20.4–48.3 seconds |
| 3Gemini | 38.9% 7 of 18 trials | 100% out of 6 tasks | — | 62.5% | 69.2 s 19–204.9 seconds |
| 4Copilot | 0% 0 of 18 trials | 100% out of 6 tasks | — | 50% | 14 s 13.8–17.1 seconds |
The real-source rate is measured only in runs that included a task asking for URLs along with the answer. For Claude, ChatGPT, Gemini and Copilot, “—” means this run did not include that kind of task. It does not mean 0%.
Trials with no answer
ChatGPT … Timed out: 4 times · Gemini … Timed out: 10 times
Refusals and timeouts stay in the base and count as incorrect. Plan limits, human verification screens and operating errors on AInformation's side are excluded from the base.
TASKS
Results by task
We sent each task to each of the 4 AIs 3 times. ○ means correct and × means incorrect. The numbers below are the seconds each trial took. Open each section to read the full task prompt, the answer key set in advance and why each verdict was given.
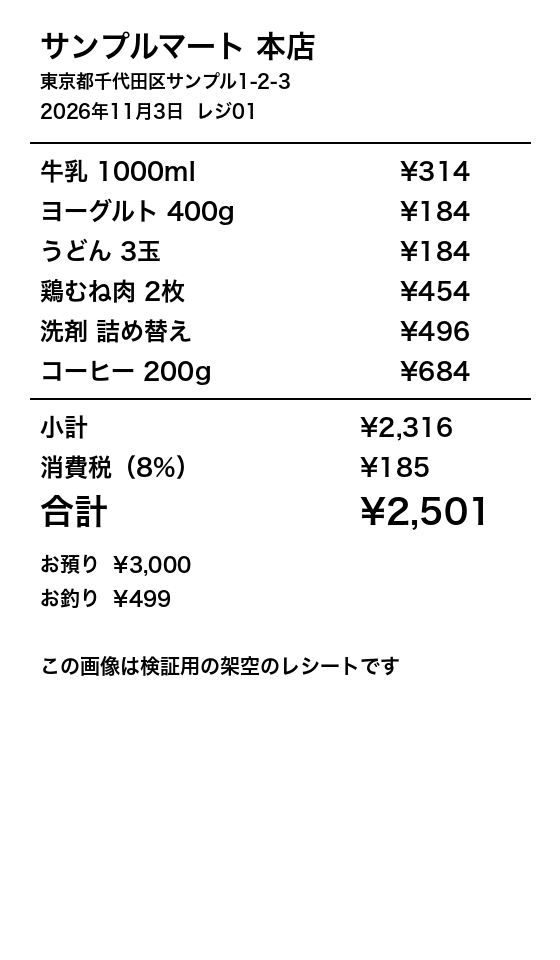
Read 3 numbers from the attached receipt image. Rules - The answer must be exactly 3 lines, in this order: Subtotal: N /… Scoring type: exact_number — Whether the number matches the correct answer. The rounding tolerance is set in advance
-
Claude
- Claude, trial 1: Correct 13.9 s
- Claude, trial 2: Correct 13.9 s
- Claude, trial 3: Correct 13.9 s
3 of 3 trials correct
-
ChatGPT
- ChatGPT, trial 1: Correct 35.8 s
- ChatGPT, trial 2: Correct 29.7 s
- ChatGPT, trial 3: Correct 20.5 s
3 of 3 trials correct
-
Gemini
- Gemini, trial 1: Incorrect 19.2 s
- Gemini, trial 2: Incorrect Timed out
- Gemini, trial 3: Incorrect Timed out
0 of 3 trials correct
-
Copilot
- Copilot, trial 1: Incorrect 14 s
- Copilot, trial 2: Incorrect 13.9 s
- Copilot, trial 3: Incorrect 13.9 s
0 of 3 trials correct
Full task promptWe sent the original Japanese version of this prompt (103 Japanese characters) unchanged to all 4 AIs. The text shown here is our translation.
Read 3 numbers from the attached receipt image. Rules - The answer must be exactly 3 lines, in this order: Subtotal: N / Consumption tax: N / Total: N - Write numbers as plain digits. No yen sign or commas needed. Do not add any explanation
Answer key set in advanceWe set it when we created the task. 2 of the 4 AIs got it right at least once
(Machine-graded exact_number) Subtotal = 2,316 (margin ±0) / Consumption tax = 185 (margin ±0) / Total = 2,501 (margin ±0)
Scoring detailsWe show, trial by trial, why each verdict was given (6 of 12 trials correct)
- Claude, trial 1: Correct
- All figures match: Subtotal ○ (correct answer 2,316) / Consumption tax ○ (correct answer 185) / Total ○ (correct answer 2,501) (13.9 seconds) · Full text of this answer (Japanese)
- Claude, trial 2: Correct
- All figures match: Subtotal ○ (correct answer 2,316) / Consumption tax ○ (correct answer 185) / Total ○ (correct answer 2,501) (13.9 seconds) · Full text of this answer (Japanese)
- Claude, trial 3: Correct
- All figures match: Subtotal ○ (correct answer 2,316) / Consumption tax ○ (correct answer 185) / Total ○ (correct answer 2,501) (13.9 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 1: Correct
- All figures match: Subtotal ○ (correct answer 2,316) / Consumption tax ○ (correct answer 185) / Total ○ (correct answer 2,501) (35.8 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 2: Correct
- All figures match: Subtotal ○ (correct answer 2,316) / Consumption tax ○ (correct answer 185) / Total ○ (correct answer 2,501) (29.7 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 3: Correct
- All figures match: Subtotal ○ (correct answer 2,316) / Consumption tax ○ (correct answer 185) / Total ○ (correct answer 2,501) (20.5 seconds) · Full text of this answer (Japanese)
- Gemini, trial 1: Incorrect
- Figures are wrong: Subtotal × (correct answer 2,316; no “Subtotal” row) / Consumption tax × (correct answer 185; no “Tax” row) / Total × (correct answer 2,501; no “Total” row) (19.2 seconds) · Full text of this answer (Japanese)
- Gemini, trial 2: Incorrect
- Timed out (the answer did not finish before the time limit) (302.6 seconds)
- Gemini, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (302.2 seconds)
- Copilot, trial 1: Incorrect
- Figures are wrong: Subtotal × (correct answer 2,316; no “Subtotal” row) / Consumption tax × (correct answer 185; no “Tax” row) / Total × (correct answer 2,501; no “Total” row) (14 seconds) · Full text of this answer (Japanese)
- Copilot, trial 2: Incorrect
- Figures are wrong: Subtotal × (correct answer 2,316; no “Subtotal” row) / Consumption tax × (correct answer 185; no “Tax” row) / Total × (correct answer 2,501; no “Total” row) (13.9 seconds) · Full text of this answer (Japanese)
- Copilot, trial 3: Incorrect
- Figures are wrong: Subtotal × (correct answer 2,316; no “Subtotal” row) / Consumption tax × (correct answer 185; no “Tax” row) / Total × (correct answer 2,501; no “Total” row) (13.9 seconds) · Full text of this answer (Japanese)
Read the change amount from the attached receipt image. Rules - The answer must be exactly 1 line, in the form Change: N… Scoring type: exact_number — Whether the number matches the correct answer. The rounding tolerance is set in advance
-
Claude
- Claude, trial 1: Correct 14.1 s
- Claude, trial 2: Correct 13.9 s
- Claude, trial 3: Correct 13.9 s
3 of 3 trials correct
-
ChatGPT
- ChatGPT, trial 1: Correct 24.1 s
- ChatGPT, trial 2: Correct 20.4 s
- ChatGPT, trial 3: Correct 20.4 s
3 of 3 trials correct
-
Gemini
- Gemini, trial 1: Correct 59.7 s
- Gemini, trial 2: Incorrect Timed out
- Gemini, trial 3: Incorrect Timed out
1 of 3 trials correct
-
Copilot
- Copilot, trial 1: Incorrect 14.1 s
- Copilot, trial 2: Incorrect 14.1 s
- Copilot, trial 3: Incorrect 13.8 s
0 of 3 trials correct
Full task promptWe sent the original Japanese version of this prompt (77 Japanese characters) unchanged to all 4 AIs. The text shown here is our translation.
Read the change amount from the attached receipt image. Rules - The answer must be exactly 1 line, in the form Change: N - Write numbers as plain digits. Do not add any explanation
Answer key set in advanceWe set it when we created the task. 3 of the 4 AIs got it right at least once
(Machine-graded exact_number) Change = 499 (margin ±0)
Scoring detailsWe show, trial by trial, why each verdict was given (7 of 12 trials correct)
- Claude, trial 1: Correct
- All figures match: Change ○ (correct answer 499) (14.1 seconds) · Full text of this answer (Japanese)
- Claude, trial 2: Correct
- All figures match: Change ○ (correct answer 499) (13.9 seconds) · Full text of this answer (Japanese)
- Claude, trial 3: Correct
- All figures match: Change ○ (correct answer 499) (13.9 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 1: Correct
- All figures match: Change ○ (correct answer 499) (24.1 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 2: Correct
- All figures match: Change ○ (correct answer 499) (20.4 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 3: Correct
- All figures match: Change ○ (correct answer 499) (20.4 seconds) · Full text of this answer (Japanese)
- Gemini, trial 1: Correct
- All figures match: Change ○ (correct answer 499) (59.7 seconds) · Full text of this answer (Japanese)
- Gemini, trial 2: Incorrect
- Timed out (the answer did not finish before the time limit) (302.3 seconds)
- Gemini, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (302.1 seconds)
- Copilot, trial 1: Incorrect
- Figures are wrong: Change × (correct answer 499; no “Change” row) (14.1 seconds) · Full text of this answer (Japanese)
- Copilot, trial 2: Incorrect
- Figures are wrong: Change × (correct answer 499; no “Change” row) (14.1 seconds) · Full text of this answer (Japanese)
- Copilot, trial 3: Incorrect
- Figures are wrong: Change × (correct answer 499; no “Change” row) (13.8 seconds) · Full text of this answer (Japanese)
List every item purchased, based on the attached receipt image. Rules - One item per line. Start each line with a bullet… Scoring type: set_match — How many of the required items were missed. Counts both omissions and made-up additions
-
Claude
- Claude, trial 1: Correct 17 s
- Claude, trial 2: Correct 13.9 s
- Claude, trial 3: Correct 13.8 s
3 of 3 trials correct
-
ChatGPT
- ChatGPT, trial 1: Correct 27.2 s
- ChatGPT, trial 2: Correct 32.8 s
- ChatGPT, trial 3: Incorrect Timed out
2 of 3 trials correct
-
Gemini
- Gemini, trial 1: Correct 189.8 s
- Gemini, trial 2: Correct 19 s
- Gemini, trial 3: Incorrect Timed out
2 of 3 trials correct
-
Copilot
- Copilot, trial 1: Incorrect 14.1 s
- Copilot, trial 2: Incorrect 13.9 s
- Copilot, trial 3: Incorrect 13.9 s
0 of 3 trials correct
Full task promptWe sent the original Japanese version of this prompt (93 Japanese characters) unchanged to all 4 AIs. The text shown here is our translation.
List every item purchased, based on the attached receipt image. Rules - One item per line. Start each line with a bullet ( · ). Write the item name and the price - Do not include the subtotal, sales tax, total, amount received, or change lines
Answer key set in advanceWe set it when we created the task. 3 of the 4 AIs got it right at least once
(Machine-graded set_match) Milk 1000ml [Milk +314] / Yogurt 400g [Yogurt +184] / Udon 3 servings [Udon +184] / Chicken breast 2 pieces [Chicken breast +454] / Detergent refill pack [Detergent +496] / Coffee 200g [Coffee +684] — up to 0 extra items allowed
Scoring detailsWe show, trial by trial, why each verdict was given (7 of 12 trials correct)
- Claude, trial 1: Correct
- All 6 items match, 0 extra items added (17 seconds) · Full text of this answer (Japanese)
- Claude, trial 2: Correct
- All 6 items match, 0 extra items added (13.9 seconds) · Full text of this answer (Japanese)
- Claude, trial 3: Correct
- All 6 items match, 0 extra items added (13.8 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 1: Correct
- All 6 items match, 0 extra items added (27.2 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 2: Correct
- All 6 items match, 0 extra items added (32.8 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (300.6 seconds)
- Gemini, trial 1: Correct
- All 6 items match, 0 extra items added (189.8 seconds) · Full text of this answer (Japanese)
- Gemini, trial 2: Correct
- All 6 items match, 0 extra items added (19 seconds) · Full text of this answer (Japanese)
- Gemini, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (302.1 seconds)
- Copilot, trial 1: Incorrect
- 0 of 6 items match; missing Milk 1000ml / Yogurt 400g / Udon 3 servings / Chicken breast 2 pieces / Detergent refill pack / Coffee 200g; 1 extra item added (14.1 seconds) · Full text of this answer (Japanese)
- Copilot, trial 2: Incorrect
- 0 of 6 items match; missing Milk 1000ml / Yogurt 400g / Udon 3 servings / Chicken breast 2 pieces / Detergent refill pack / Coffee 200g; 1 extra item added (13.9 seconds) · Full text of this answer (Japanese)
- Copilot, trial 3: Incorrect
- 0 of 6 items match; missing Milk 1000ml / Yogurt 400g / Udon 3 servings / Chicken breast 2 pieces / Detergent refill pack / Coffee 200g; 1 extra item added (13.9 seconds) · Full text of this answer (Japanese)
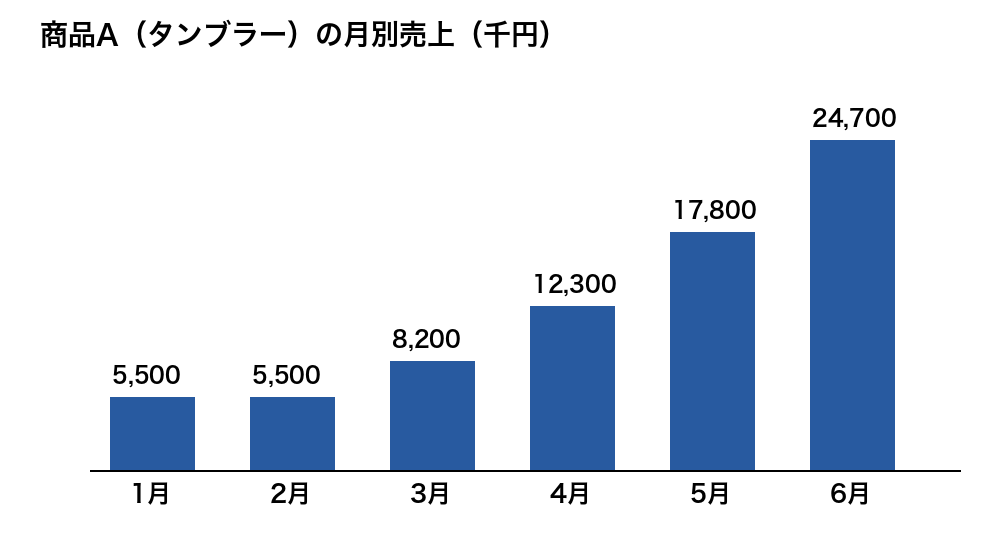
Looking at the attached bar chart image, which month has the tallest bar? Rules - The answer must be exactly 1 line: jus… Scoring type: contains_all — Whether all the required words and phrases are included
-
Claude
- Claude, trial 1: Correct 13.9 s
- Claude, trial 2: Correct 13.8 s
- Claude, trial 3: Correct 13.9 s
3 of 3 trials correct
-
ChatGPT
- ChatGPT, trial 1: Correct 26.7 s
- ChatGPT, trial 2: Correct 48.3 s
- ChatGPT, trial 3: Incorrect Timed out
2 of 3 trials correct
-
Gemini
- Gemini, trial 1: Correct 61.7 s
- Gemini, trial 2: Incorrect Timed out
- Gemini, trial 3: Correct 76.7 s
2 of 3 trials correct
-
Copilot
- Copilot, trial 1: Incorrect 13.9 s
- Copilot, trial 2: Incorrect 14 s
- Copilot, trial 3: Incorrect 14 s
0 of 3 trials correct
Full task promptWe sent the original Japanese version of this prompt (64 Japanese characters) unchanged to all 4 AIs. The text shown here is our translation.
Looking at the attached bar chart image, which month has the tallest bar? Rules - The answer must be exactly 1 line: just the month name (for example, January) - Do not include numeric values or any explanation
Answer key set in advanceWe set it when we created the task. 3 of the 4 AIs got it right at least once
(Machine-graded contains_all) Highest month = June
Scoring detailsWe show, trial by trial, why each verdict was given (7 of 12 trials correct)
- Claude, trial 1: Correct
- The one item was present (13.9 seconds) · Full text of this answer (Japanese)
- Claude, trial 2: Correct
- The one item was present (13.8 seconds) · Full text of this answer (Japanese)
- Claude, trial 3: Correct
- The one item was present (13.9 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 1: Correct
- The one item was present (26.7 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 2: Correct
- The one item was present (48.3 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (300.8 seconds)
- Gemini, trial 1: Correct
- The one item was present (61.7 seconds) · Full text of this answer (Japanese)
- Gemini, trial 2: Incorrect
- Timed out (the answer did not finish before the time limit) (302.2 seconds)
- Gemini, trial 3: Correct
- The one item was present (76.7 seconds) · Full text of this answer (Japanese)
- Copilot, trial 1: Incorrect
- 0 of 1 item present; missing “highest month” (13.9 seconds) · Full text of this answer (Japanese)
- Copilot, trial 2: Incorrect
- 0 of 1 item present; missing “highest month” (14 seconds) · Full text of this answer (Japanese)
- Copilot, trial 3: Incorrect
- 0 of 1 item present; missing “highest month” (14 seconds) · Full text of this answer (Japanese)
From the attached bar chart image, read off every monthly value. Rules - One line per month, in the format Month: Value,… Scoring type: exact_number — Whether the number matches the correct answer. The rounding tolerance is set in advance
-
Claude
- Claude, trial 1: Correct 13.9 s
- Claude, trial 2: Correct 13.9 s
- Claude, trial 3: Correct 13.9 s
3 of 3 trials correct
-
ChatGPT
- ChatGPT, trial 1: Correct 20.5 s
- ChatGPT, trial 2: Correct 26.6 s
- ChatGPT, trial 3: Incorrect Timed out
2 of 3 trials correct
-
Gemini
- Gemini, trial 1: Correct 204.9 s
- Gemini, trial 2: Incorrect Timed out
- Gemini, trial 3: Incorrect Timed out
1 of 3 trials correct
-
Copilot
- Copilot, trial 1: Incorrect 14 s
- Copilot, trial 2: Incorrect 13.9 s
- Copilot, trial 3: Incorrect 13.9 s
0 of 3 trials correct
Full task promptWe sent the original Japanese version of this prompt (85 Japanese characters) unchanged to all 4 AIs. The text shown here is our translation.
From the attached bar chart image, read off every monthly value. Rules - One line per month, in the format Month: Value, listed from left to right - Write numbers using standard digits. Do not add any explanation
Answer key set in advanceWe set it when we created the task. 3 of the 4 AIs got it right at least once
(Machine-graded exact_number) January = 5,500 (margin ±0) / February = 5,500 (margin ±0) / March = 8,200 (margin ±0) / April = 12,300 (margin ±0) / May = 17,800 (margin ±0) / June = 24,700 (margin ±0)
Scoring detailsWe show, trial by trial, why each verdict was given (6 of 12 trials correct)
- Claude, trial 1: Correct
- All figures match: January ○ (correct answer 5,500) / February ○ (correct answer 5,500) / March ○ (correct answer 8,200) / April ○ (correct answer 12,300) / May ○ (correct answer 17,800) / June ○ (correct answer 24,700) (13.9 seconds) · Full text of this answer (Japanese)
- Claude, trial 2: Correct
- All figures match: January ○ (correct answer 5,500) / February ○ (correct answer 5,500) / March ○ (correct answer 8,200) / April ○ (correct answer 12,300) / May ○ (correct answer 17,800) / June ○ (correct answer 24,700) (13.9 seconds) · Full text of this answer (Japanese)
- Claude, trial 3: Correct
- All figures match: January ○ (correct answer 5,500) / February ○ (correct answer 5,500) / March ○ (correct answer 8,200) / April ○ (correct answer 12,300) / May ○ (correct answer 17,800) / June ○ (correct answer 24,700) (13.9 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 1: Correct
- All figures match: January ○ (correct answer 5,500) / February ○ (correct answer 5,500) / March ○ (correct answer 8,200) / April ○ (correct answer 12,300) / May ○ (correct answer 17,800) / June ○ (correct answer 24,700) (20.5 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 2: Correct
- All figures match: January ○ (correct answer 5,500) / February ○ (correct answer 5,500) / March ○ (correct answer 8,200) / April ○ (correct answer 12,300) / May ○ (correct answer 17,800) / June ○ (correct answer 24,700) (26.6 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (300.8 seconds)
- Gemini, trial 1: Correct
- All figures match: January ○ (correct answer 5,500) / February ○ (correct answer 5,500) / March ○ (correct answer 8,200) / April ○ (correct answer 12,300) / May ○ (correct answer 17,800) / June ○ (correct answer 24,700) (204.9 seconds) · Full text of this answer (Japanese)
- Gemini, trial 2: Incorrect
- Timed out (the answer did not finish before the time limit) (302.1 seconds)
- Gemini, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (302.3 seconds)
- Copilot, trial 1: Incorrect
- Figures are wrong: January × (correct answer 5,500; no “January” row) / February × (correct answer 5,500; no “February” row) / March × (correct answer 8,200; no “March” row) / April × (correct answer 12,300; no “April” row) / May × (correct answer 17,800; no “May” row) / June × (correct answer 24,700; no “June” row) (14 seconds) · Full text of this answer (Japanese)
- Copilot, trial 2: Incorrect
- Figures are wrong: January × (correct answer 5,500; no “January” row) / February × (correct answer 5,500; no “February” row) / March × (correct answer 8,200; no “March” row) / April × (correct answer 12,300; no “April” row) / May × (correct answer 17,800; no “May” row) / June × (correct answer 24,700; no “June” row) (13.9 seconds) · Full text of this answer (Japanese)
- Copilot, trial 3: Incorrect
- Figures are wrong: January × (correct answer 5,500; no “January” row) / February × (correct answer 5,500; no “February” row) / March × (correct answer 8,200; no “March” row) / April × (correct answer 12,300; no “April” row) / May × (correct answer 17,800; no “May” row) / June × (correct answer 24,700; no “June” row) (13.9 seconds) · Full text of this answer (Japanese)
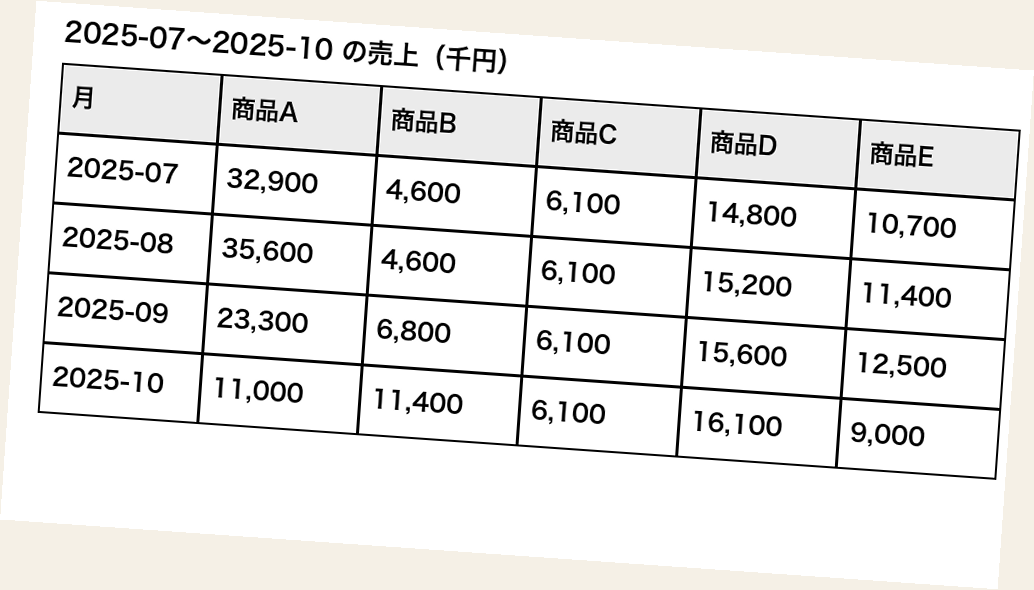
Read all the values in the Product A column from the attached table image (which is slightly tilted). Rules - One value … Scoring type: exact_number — Whether the number matches the correct answer. The rounding tolerance is set in advance
-
Claude
- Claude, trial 1: Correct 17.1 s
- Claude, trial 2: Correct 17 s
- Claude, trial 3: Correct 16.9 s
3 of 3 trials correct
-
ChatGPT
- ChatGPT, trial 1: Incorrect 20.6 s
- ChatGPT, trial 2: Correct 20.5 s
- ChatGPT, trial 3: Incorrect Timed out
1 of 3 trials correct
-
Gemini
- Gemini, trial 1: Correct 134.9 s
- Gemini, trial 2: Incorrect Timed out
- Gemini, trial 3: Incorrect Timed out
1 of 3 trials correct
-
Copilot
- Copilot, trial 1: Incorrect 14 s
- Copilot, trial 2: Incorrect 17.1 s
- Copilot, trial 3: Incorrect 14 s
0 of 3 trials correct
Full task promptWe sent the original Japanese version of this prompt (92 Japanese characters) unchanged to all 4 AIs. The text shown here is our translation.
Read all the values in the Product A column from the attached table image (which is slightly tilted). Rules - One value per line, in the form Month: N, from top to bottom - Write numbers as plain digits. Do not add any explanation
Answer key set in advanceWe set it when we created the task. 3 of the 4 AIs got it right at least once
(Machine-graded exact_number) 2025-07 = 32,900 (margin ±0) / 2025-08 = 35,600 (margin ±0) / 2025-09 = 23,300 (margin ±0) / 2025-10 = 11,000 (margin ±0)
Scoring detailsWe show, trial by trial, why each verdict was given (5 of 12 trials correct)
- Claude, trial 1: Correct
- All figures match: 2025-07 ○ (correct answer 32,900) / 2025-08 ○ (correct answer 35,600) / 2025-09 ○ (correct answer 23,300) / 2025-10 ○ (correct answer 11,000) (17.1 seconds) · Full text of this answer (Japanese)
- Claude, trial 2: Correct
- All figures match: 2025-07 ○ (correct answer 32,900) / 2025-08 ○ (correct answer 35,600) / 2025-09 ○ (correct answer 23,300) / 2025-10 ○ (correct answer 11,000) (17 seconds) · Full text of this answer (Japanese)
- Claude, trial 3: Correct
- All figures match: 2025-07 ○ (correct answer 32,900) / 2025-08 ○ (correct answer 35,600) / 2025-09 ○ (correct answer 23,300) / 2025-10 ○ (correct answer 11,000) (16.9 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 1: Incorrect
- Figures are wrong: 2025-07 × (correct answer 32,900; no “2025-07” row) / 2025-08 × (correct answer 35,600; no “2025-08” row) / 2025-09 × (correct answer 23,300; no “2025-09” row) / 2025-10 × (correct answer 11,000; no “2025-10” row) (20.6 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 2: Correct
- All figures match: 2025-07 ○ (correct answer 32,900) / 2025-08 ○ (correct answer 35,600) / 2025-09 ○ (correct answer 23,300) / 2025-10 ○ (correct answer 11,000) (20.5 seconds) · Full text of this answer (Japanese)
- ChatGPT, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (301.2 seconds)
- Gemini, trial 1: Correct
- All figures match: 2025-07 ○ (correct answer 32,900) / 2025-08 ○ (correct answer 35,600) / 2025-09 ○ (correct answer 23,300) / 2025-10 ○ (correct answer 11,000) (134.9 seconds) · Full text of this answer (Japanese)
- Gemini, trial 2: Incorrect
- Timed out (the answer did not finish before the time limit) (302.1 seconds)
- Gemini, trial 3: Incorrect
- Timed out (the answer did not finish before the time limit) (302.5 seconds)
- Copilot, trial 1: Incorrect
- Figures are wrong: 2025-07 × (correct answer 32,900; no “2025-07” row) / 2025-08 × (correct answer 35,600; no “2025-08” row) / 2025-09 × (correct answer 23,300; no “2025-09” row) / 2025-10 × (correct answer 11,000; no “2025-10” row) (14 seconds) · Full text of this answer (Japanese)
- Copilot, trial 2: Incorrect
- Figures are wrong: 2025-07 × (correct answer 32,900; no “2025-07” row) / 2025-08 × (correct answer 35,600; no “2025-08” row) / 2025-09 × (correct answer 23,300; no “2025-09” row) / 2025-10 × (correct answer 11,000; no “2025-10” row) (17.1 seconds) · Full text of this answer (Japanese)
- Copilot, trial 3: Incorrect
- Figures are wrong: 2025-07 × (correct answer 32,900; no “2025-07” row) / 2025-08 × (correct answer 35,600; no “2025-08” row) / 2025-09 × (correct answer 23,300; no “2025-09” row) / 2025-10 × (correct answer 11,000; no “2025-10” row) (14 seconds) · Full text of this answer (Japanese)
ANSWERS
Full answers from the 4 AIs
These are the answers we scored, posted as is without edits. That way, anyone can recount the results the same way we did.
-
Claude
18 answers18 of them correct
- t1, trial 1
- Full text file (Japanese) · Correct
- t1, trial 2
- Full text file (Japanese) · Correct
- t1, trial 3
- Full text file (Japanese) · Correct
- t2, trial 1
- Full text file (Japanese) · Correct
- t2, trial 2
- Full text file (Japanese) · Correct
- t2, trial 3
- Full text file (Japanese) · Correct
- t3, trial 1
- Full text file (Japanese) · Correct
- t3, trial 2
- Full text file (Japanese) · Correct
- t3, trial 3
- Full text file (Japanese) · Correct
- t4, trial 1
- Full text file (Japanese) · Correct
- t4, trial 2
- Full text file (Japanese) · Correct
- t4, trial 3
- Full text file (Japanese) · Correct
- t5, trial 1
- Full text file (Japanese) · Correct
- t5, trial 2
- Full text file (Japanese) · Correct
- t5, trial 3
- Full text file (Japanese) · Correct
- t6, trial 1
- Full text file (Japanese) · Correct
- t6, trial 2
- Full text file (Japanese) · Correct
- t6, trial 3
- Full text file (Japanese) · Correct
-
ChatGPT
14 answers13 of them correct
- t1, trial 1
- Full text file (Japanese) · Correct
- t1, trial 2
- Full text file (Japanese) · Correct
- t1, trial 3
- Full text file (Japanese) · Correct
- t2, trial 1
- Full text file (Japanese) · Correct
- t2, trial 2
- Full text file (Japanese) · Correct
- t2, trial 3
- Full text file (Japanese) · Correct
- t3, trial 1
- Full text file (Japanese) · Correct
- t3, trial 2
- Full text file (Japanese) · Correct
- t4, trial 1
- Full text file (Japanese) · Correct
- t4, trial 2
- Full text file (Japanese) · Correct
- t5, trial 1
- Full text file (Japanese) · Correct
- t5, trial 2
- Full text file (Japanese) · Correct
- t6, trial 1
- Full text file (Japanese) · Incorrect
- t6, trial 2
- Full text file (Japanese) · Correct
-
Gemini
8 answers7 of them correct
- t1, trial 1
- Full text file (Japanese) · Incorrect
- t2, trial 1
- Full text file (Japanese) · Correct
- t3, trial 1
- Full text file (Japanese) · Correct
- t3, trial 2
- Full text file (Japanese) · Correct
- t4, trial 1
- Full text file (Japanese) · Correct
- t4, trial 3
- Full text file (Japanese) · Correct
- t5, trial 1
- Full text file (Japanese) · Correct
- t6, trial 1
- Full text file (Japanese) · Correct
-
Copilot
18 answers0 of them correct
- t1, trial 1
- Full text file (Japanese) · Incorrect
- t1, trial 2
- Full text file (Japanese) · Incorrect
- t1, trial 3
- Full text file (Japanese) · Incorrect
- t2, trial 1
- Full text file (Japanese) · Incorrect
- t2, trial 2
- Full text file (Japanese) · Incorrect
- t2, trial 3
- Full text file (Japanese) · Incorrect
- t3, trial 1
- Full text file (Japanese) · Incorrect
- t3, trial 2
- Full text file (Japanese) · Incorrect
- t3, trial 3
- Full text file (Japanese) · Incorrect
- t4, trial 1
- Full text file (Japanese) · Incorrect
- t4, trial 2
- Full text file (Japanese) · Incorrect
- t4, trial 3
- Full text file (Japanese) · Incorrect
- t5, trial 1
- Full text file (Japanese) · Incorrect
- t5, trial 2
- Full text file (Japanese) · Incorrect
- t5, trial 3
- Full text file (Japanese) · Incorrect
- t6, trial 1
- Full text file (Japanese) · Incorrect
- t6, trial 2
- Full text file (Japanese) · Incorrect
- t6, trial 3
- Full text file (Japanese) · Incorrect
MATERIALS
Materials used in the tasks
Original images we created ourselves: a receipt photo, a bar chart image, and a slightly tilted table image. The original numbers were set when we created them We recreated them for this run on November 2, 2026. Download them to repeat the same test yourself.
- chart.png 24KB (Japanese)
- receipt.png 67KB (Japanese)
- table_photo.png 128KB (Japanese)
METHOD
How we measure
We list this run's conditions exactly as they were, so anyone can repeat it.
AIs measured and their model names at the time
AI services change under the hood without notice. We record the model name shown on screen and the time we checked it.
| AI | Plan | Model name shown on screen | Time checked |
|---|---|---|---|
| ChatGPT | ChatGPT Pro | GPT-6.1 Sol Medium | 2026-11-02 21:03 |
| Gemini | Google AI Pro | Flash | 2026-11-02 21:03 |
| Claude | Claude Max | Opus 4.8 High | 2026-11-02 21:03 |
| Copilot | Microsoft 365 Personal | 2026-11-02 21:03 |
What we did in this run
- We recreated the materials for the tasks specifically for this run. The data are for a fictional company and include no real companies or people.
- We created 6 tasks and set the answer keys at that point.
- We sent the same prompt and the same materials to ChatGPT, Gemini, Claude and Copilot.
- We sent each task 3 times, in a new chat each time.
- We rotated the sending order from run to run. This keeps the time of day from skewing the ranking.
- We waited up to 300 seconds for each answer, and recorded anything longer as a timeout.
- Scoring: Machine scoring only (not graded by AI).
- We sent 72 trials in total, and 72 of them were valid.
How we count trials with no answer
- Refused or timed out
We keep it in the base and count it as wrong. Because at work, that is the same as getting no answer.
- Hit the plan's usage limit
We remove it from the base. We treat that trial as not measured.
- A human verification screen appeared
We stop there. We neither click through it automatically nor try to get around it.
- Operating error on AInformation's side
We remove it from the base. We do not report it as the AI's fault.
LIMITS
Limits of this benchmark
So that no one judges by the numbers alone, we list what we could not measure.
- This is a single run on a single day. Rankings can change with the day or the task
- The plan used is each AI's paid tier (ChatGPT Pro / Google AI Pro / Claude Max / Microsoft 365 Personal). These are not results from the free tier
- Measurements use only the default model and default mode (features such as Deep Research are not used)
- The tasks use original data for the fictional company Sample Shoji Co., Ltd. These are not results using data from a real company
- Only tasks that can be scored by machine are covered. Writing quality and readability are not measured
- Measurements are taken from the same screen a person would use in a browser. These are not results from the API
- For any AI whose on-screen model name could not be read in a given run, that field is left blank (null). When the name could be read, it is shown as is
DATA
Published data
In the CSV, 1 row is 1 trial. The figures on this page match a recount of that CSV. The license is CC BY 4.0.
- Latest version (CSV) (Japanese) 1 row = 1 trial, 16KB
- Latest version (JSON) 38KB
- v1 (version at publication) (CSV) (Japanese) 1 row = 1 trial, 16KB
- v1 (version at publication) (JSON) 38KB
The cumulative rankings are at /en/data/research/bench/leaderboard.json. We do not delete versions (such as v1). That way, links from people who cited them keep working.
FAQ
FAQ
- How do you measure?
- We send exactly the same task prompt and the same materials to the 4 AIs on the same day. We open a new chat every time so earlier answers don't carry over. The sending order is rotated in each run. We also record the seconds from sending until the answer stops.
- Why do you send the same task 3 times?
- Because AI answers vary even for the same question. From a single try, you can't tell whether a result reflects real ability or chance. We send each task 3 times, and the share of tasks whose conclusion matched is reported as the consistency rate.
- Who does the scoring?
- Scoring is done only by a program. We do not let AI score the answers. The correct answers are set when the tasks are created, and whether an answer is right is decided by whether numbers match, whether required words are present, whether the format fits, whether URLs actually open and the result of running formulas. Matters of taste are not scored.
- Is the data in the tasks from real companies?
- No. We create new data for a fictional company every time. We do not use real companies, real people or text from other companies. We share the materials we used as they are, so you can repeat the same test.
- How do you count cases where the AI couldn't answer?
- Refusals and timeouts stay in the base and are counted as wrong. If we hit the plan's usage limit or a human verification screen appears, we remove that trial from the base and treat it as not measured. Operating errors on AInformation's side are also removed from the base, and we do not report them as the AI's fault.
- Do you use the free or paid versions?
- We use each AI's paid plan through the browser interface. We don't use the API. For each run, we record the plan name, the model name shown on screen and the time we checked it.
- Does this ranking show which AI is the smartest?
- No. We measure only 5 things on a fixed set of work tasks: accuracy, time to answer, consistency rate, real-source rate and instruction compliance. We do not measure writing style, readability or behavior in long conversations. If the tasks change, the ranking changes too.
- Can I cite these results?
- Yes. The license is CC BY 4.0. As the source, please write “Source: AInformation, AI Practical Work Benchmark” with the URL of the page you used and the measurement date. The results are also available as JSON and CSV. With the CSV (1 row per trial), you can recount the figures we publish.
CITATION
Cite this benchmark
Source: AInformation, “AI Practical Work Benchmark: Reading numbers from images of receipts, charts, and tables (4 AIs, 6 tasks, 3 runs each)” (https://ainformation.jp/en/ai-surveys/ai-work-benchmark/numbers-from-images-2026-11-03). Measured on November 3, 2026. 6 tasks, 3 trials each, 72 valid trials
Copied
When you cite a figure, please include the base too (how many of how many trials). Please cite AInformation as the source, along with the URL of the page you used and the measurement date.
Related pages
The latest AI news, rounded up once a week
One email with the week's main AI news and the tools AInformation's editors actually tried.